Edge Delta benchmarks
Open, neutral benchmarks for AI incident reasoning and observability pipeline performance. Every model gets the same data and the same tools. We measure the reasoning.
AI SRE Arena · vendor benchmark · v1
Edge Delta and Grafana on the same 21 Kubernetes incidents
Each product found and investigated injected faults with its own collectors and alerting, and every final report was judged against the same answer key.
Read the report →
Golden Threads Fine-Tune
Can a small model you host yourself diagnose real incidents?
Field notes
Same bug, four minds
One production panic paged four frontier-model agent teams at the same instant. Same diagnosis, same one-line fix, four different definitions of done. A behavioral teardown of a single real incident, model by model.
Read the teardown →Field notes
Small model, home turf
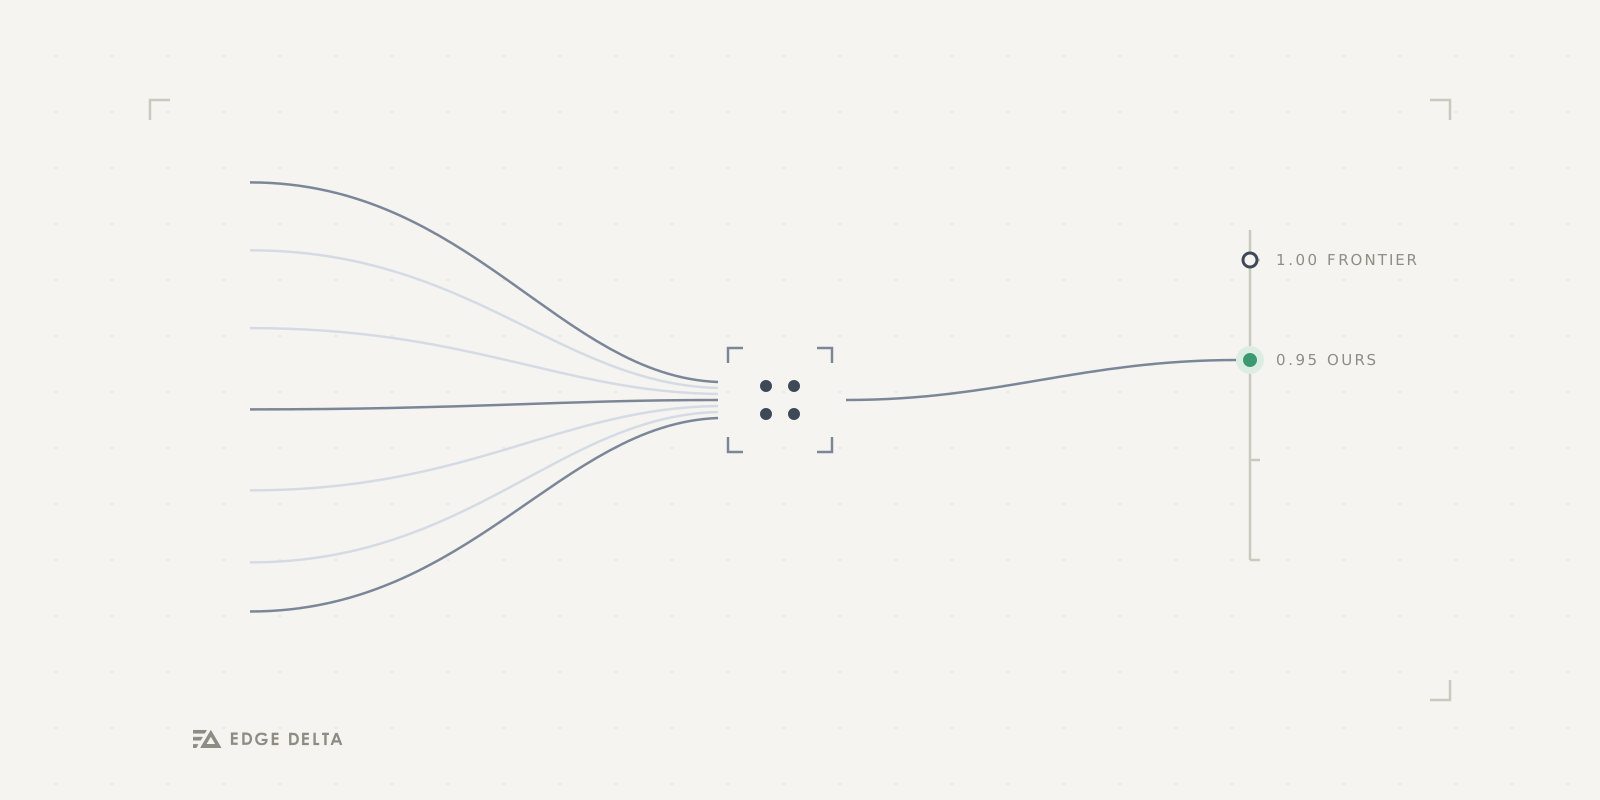
We fine-tuned Qwen3-32B on golden threads distilled from real Edge Delta investigations, then scored it against its base, a 235B model, and the GPT-5.5 frontier on 50 root-cause scenarios. A case study in specializing a small model for incident diagnosis.
Read the case study →See Edge Delta in action
Get hands-on in our interactive playground environment.