Gartner has named Edge Delta a Leader in the 2026 Gartner® Magic Quadrant™ for Observability Pipelines1.
Most vendor posts about a Magic Quadrant stop at the badge. I want to spend this one on the road, because the road is where the useful lessons are. When we started Edge Delta in 2018 there was no such category. There was no Market Guide, no reviews page, and no analyst who would take a briefing about “pipelines” without first asking which logging vendor we were going to replace. Getting from there to a Leader placement took eight years, a few bets that looked strange at the time, and a market that eventually came around to the same conclusion we had reached.
2018: the bet that data should start to be processed where it is created
I spent close to five years at Sumo Logic as a trusted technical advisor to the most innovative companies in the world, helping enable centralized log analytics. By the end of that stretch the pattern in every engineering team across every company was the same. Volumes were growing faster than budgets, the ingest license had become a ceiling on visibility, and teams were aggressively pruning, sampling, or even downright turning off logging for entire services because of the financial and technical challenges to index all of it. The products in the space, Splunk, Elastic, Sumo Logic were good, but the architectural concept of post-index intelligence had started to run into limitations.
Fatih Yildiz and I had met over a decade earlier as software developers at Microsoft, and he had spent the time since running some of the most massive real-time prod environments at Twitter. We founded Edge Delta on one premise: the right place to evaluate telemetry is the place it is generated. If an agent on the host can parse, aggregate, detect anomalies, and decide what deserves to be shipped, then centralization becomes a choice rather than a tax.
MaC Venture Capital and Amity Ventures led our seed round on that premise. Their own write-up from 2019, The Rise of the Edge (Delta), still reads as a decent summary of the thesis: outages cost real money, most generated data never gets analyzed, and moving the initiation of analysis upstream to the source makes it economical to look at all of it.
2021: Edge Delta leads as the first and only intelligent observability pipelines
“The innovative approach allows DevOps, Security, and SRE teams to analyze large volumes of streaming data without the cost, delay, or complexity of requiring data to be indexed, helping customers decouple where machine data is analyzed from where it is stored” - that was a quote from our press release nearly five years ago, Edge Delta Releases Intelligent Observability Pipelines for DevOps, Security, and SRE teams, and the concepts were later proven to be a foundational part of the future. There was simply too much benefit to a more tactical approach to preprocessing real time prod data streams. Sometimes you simply don’t need every log, metric, or trace in your premium high cost storage tier, and even in 2021 these problems were breaking the teams that were running observability at scale.
This is a large reason why we partnered with Matt Murphy, Tim Tully, and Menlo Ventures, in our Series A: Edge Delta raises $15M Series A to take on Splunk. Today they are some of the earliest and largest investors in Anthropic, and we were fortunate in 2021 that they saw many of the challenges in observability the same way we did. We continue to build on the same premise. As the entire world has moved aggressively into the agentic era (for good reasons), with orders of magnitude more code being written, merged, deployed, and productionized, the core concepts that Edge Delta was built on are becoming a necessity, but more on that later.
2022: the bet scales
By May 2022 the thesis had enough customer proof behind it to raise a $63 million Series B led by Quiet Capital, with ServiceNow and Cisco among the new investors and continued participation from existing investors. At the time we described ourselves as being an “edge observability” platform. This is where the pipelines live. What mattered was that distributed stream processing was now running in production for DevOps, SRE and security teams at real scale, and the cost and MTTR numbers were hugely improving for our customers. They wanted to route a copy to S3, send an optimized stream to Splunk or Datadog, turn noisy logs into metrics, and redact sensitive fields on the way out.
2023: Gartner gives the idea a name
In September 2023 Gartner recognized Edge Delta as a Cool Vendor in Monitoring and Observability2. We were proud of it, but the more important event that year was quieter. Gartner started using the phrase “telemetry pipelines” to describe a distinct class of tool that sits between collection and storage, and published a prediction that by 2026, 40% of log telemetry would be processed through a telemetry pipeline product3.
A prediction like that changes conversations. Buyers stopped asking whether a pipeline was a feature of their logging vendor and started asking which pipeline they should run. We wanted to support the OpenTelemetry movement through and through, so we renamed the product to Telemetry Pipelines, rebuilt the pipeline builder around a visual graph, and made OpenTelemetry the native data model rather than an integration. If you want a snapshot of our thinking at the time, What Are Telemetry Pipelines? and How Edge Delta’s Telemetry Pipelines Architecture Delivers Cost Savings and Efficiency are both from this stretch.
2025: the category gets a Market Guide
Gartner published its Market Guide for Telemetry Pipelines on 2 September 20254. A Market Guide is the step before a Magic Quadrant. It means the analysts consider the market real, growing and worth tracking, but not yet mature enough to rank. For us it was confirmation that the thing we had been building since 2018 now had a definition the whole industry would be measured against.
It also raised the bar. Once a category is defined, every vendor can claim to be in it. Logging platforms added routing. Collectors added processors. Security vendors shipped data pipelines for SIEM cost control and data enrichment. The differentiation had to move from “we have a pipeline” to “what does the pipeline know, and what can it do with that knowledge”. That became the question we organized the next year of roadmap around.
2026: the magical moment
Three things happened this year that, in our view, set up the Leader placement.
First, Gartner renamed the market. Its reviews category is now titled “Telemetry Pipelines (Transitioning to Observability Pipelines)”, and in April it published a Market Overview for Observability Pipelines5. The rename matters. “Telemetry” describes the input. “Observability” describes the outcome. A pipeline that only moves bytes from A to B cheaply is a collector. A pipeline that understands the data well enough to produce patterns, metrics, anomalies and context on the way through is an observability tool in its own right.
Second, we made Telemetry Pipelines data throughput free at any scale. The economics of the category had been stuck on a contradiction: vendors charged per gigabyte for a product whose whole purpose was to reduce gigabytes. Removing the throughput meter let customers process everything at the source without doing arithmetic on every new service they onboarded.
Third, we put AI on top of the pipeline rather than beside it. In February I wrote about Observability 3.0, the idea that the next bottleneck is making sense of telemetry and acting on it, and that AI agents need a pipeline underneath them for two reasons. They need rich, structured, already-processed data to reason over, and they need a control point that decides which data they are allowed to see. Our pipelines became that control point, and our AI agents became the most demanding consumer of what the pipelines produce.
What we think Gartner saw
Gartner evaluates vendors on Ability to Execute and Completeness of Vision, and the report explains its own criteria far better than I can. I will offer our read on why the architecture we chose in 2018 lines up with where the category landed.
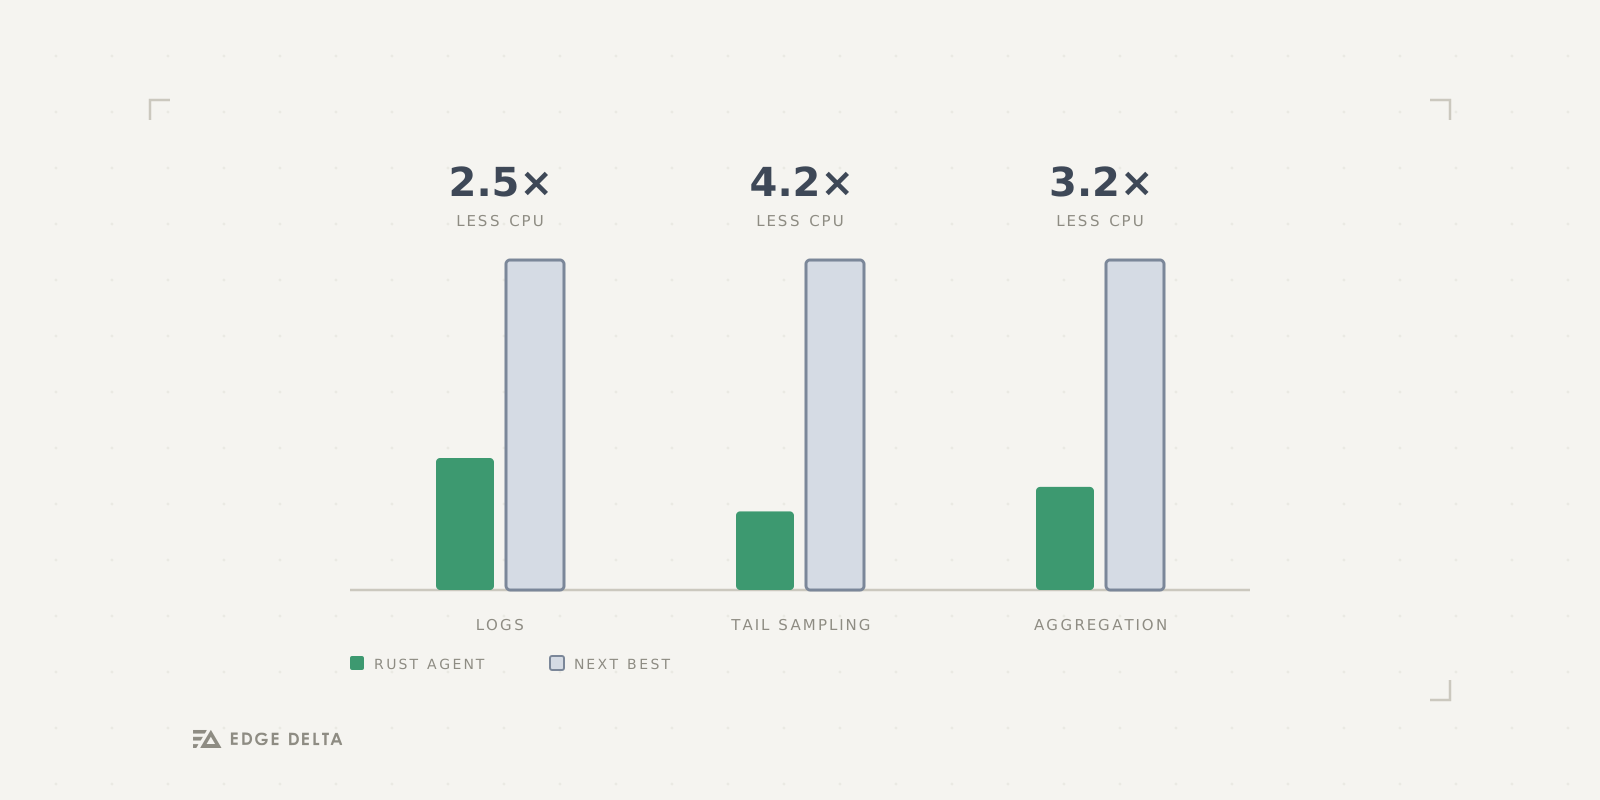
- Processing at the source, by design. Every other approach we have seen bolts a pipeline onto a centralized platform. Ours started distributed, so the agent on the host has always done the work: parsing, aggregation, pattern detection, PII masking and routing happen before a byte leaves the environment.
- Open standards as the native model. OpenTelemetry, OTTL and OCSF are the data model and the transformation language, not export formats. That keeps customers portable and lets them route to any backend, including ones that compete with us.
- Intelligence inside the pipeline. Recommendations, anomaly detection and pattern clustering run in the pipeline itself. The pipeline is where the data is richest and the decision is cheapest. This pairs well with centralized correlation.
- A pipeline that feeds agents. Our agents investigate incidents using the patterns, metrics and enriched events the pipelines produce. The two products make each other better, and customers see that as one platform rather than a bundle.
- Pricing that matches the job. Throughput is free, so the incentive to process more data at the source is aligned with ours instead of against it.
We believe these were the themes that mattered, and we believe they will keep mattering as the Magic Quadrant matures.
What this means for the people who run production
A Magic Quadrant placement is a marketing asset, and I will not pretend otherwise, but here is the part that is actually useful if you operate prod systems for a living: the pipeline is now the layer where cost, compliance and AI readiness all get decided. If your pipeline is a thin forwarder, each of those is somebody else’s problem downstream, and downstream is where things are expensive. If your pipeline understands the data, you decide what gets indexed, what gets archived, what gets redacted, and what an agent is allowed to reason over, all in one place and before the bill arrives.
Things just don’t fit all nicely in a box anymore, intelligent and dynamic pipelines are the standard we think the category should be held to, and the standard we intend to keep raising. Being named a Leader is a milestone on that road, and we’re excited where that road leads.
See it for yourself
If you would rather see the pipeline than read about it, create a free account and route your first stream in a few minutes.
To our customers, partners and team: thank you. You are the reason the bet paid off.
Sources
GARTNER and MAGIC QUADRANT are registered trademarks and service marks of Gartner, Inc. and/or its affiliates in the U.S. and internationally, and COOL VENDORS is a registered trademark of Gartner, Inc. and/or its affiliates and are used herein with permission. All rights reserved. Gartner does not endorse any vendor, product or service depicted in its research publications, and does not advise technology users to select only those vendors with the highest ratings or other designation. Gartner research publications consist of the opinions of Gartner’s research organization and should not be construed as statements of fact. Gartner disclaims all warranties, expressed or implied, with respect to this research, including any warranties of merchantability or fitness for a particular purpose.
Footnotes
-
Gartner, Magic Quadrant for Observability Pipelines, by Pankaj Prasad, Andre Bridges, Andrea Curry, Neil Young, published 12 November 2026. ↩
-
Gartner, Cool Vendors in Monitoring and Observability, by Gregg Siegfried, Mrudula Bangera, Padraig Byrne, Hassan Ennaciri, Pankaj Prasad, Dylan Roberts, published 25 September 2023. ↩
-
Gartner, Innovation Insight: Telemetry Pipelines Elevate the Handling of Operational Data, by Gregg Siegfried, published 20 July 2023. ↩
-
Gartner, Market Guide for Telemetry Pipelines, published 2 September 2025. ↩
-
Gartner, Market Overview for Observability Pipelines, published 3 April 2026. ↩